Configuring winnoise “” correctly is the difference between a setup that feels effortless and one that needs constant tweaking. If you searched for “Configuration Options and Best Practices,” you likely want practical guidance: what to configure, what each option means, and how to avoid the most common failure modes.
This supporting guide focuses on one clear long-tail goal: getting a stable, predictable configuration for winnoise “” by understanding the options that matter most. It complements a broader pillar resource by going deeper into setup decisions, rollout habits, and day-to-day operational best practices.
Start with the outcome you want from winnoise “”
Before you touch any settings, decide what “good” looks like for your use case. Configuration decisions should be driven by user experience goals (latency, responsiveness, consistency) and operational goals (maintainability, debuggability, cost control).
Many misconfigurations come from selecting defaults that were convenient at the start but don’t match your real workload. Take a few minutes to outline your expected traffic patterns, success criteria, and the constraints you must respect.
Think in terms of requirements rather than features. If you need stable performance under varying load, you will prioritize predictable behavior and conservative limits. If you need maximum flexibility, you may accept more tuning overhead in exchange for adaptability.
Core configuration options: how to choose the right values
Most configurations for winnoise “” can be understood as three layers: input handling, processing behavior, and output/interaction patterns. You will typically see options that influence how data is received, how it is transformed or routed, and how results are delivered.
In practice, the best approach is to set safe baseline values first, then tune only the parameters that directly affect your performance bottlenecks. That prevents “optimization drift,” where small changes add complexity without meaningful improvements.
As you evaluate each option, ask two questions: “What does this control?” and “What will break if I set it wrong?” That framing makes it easier to avoid chasing symptoms rather than causes.
For example, if there are configuration options for limits (such as maximum sizes, timeouts, concurrency controls, or retry behavior), treat them like guardrails. Guardrails reduce the chance of cascading failures when something unexpected happens, such as bursts of traffic or unusually large payloads.
If the configuration includes toggles that change processing modes (for instance, whether to enable certain features, choose different routing logic, or adjust workflow steps), start by matching the simplest mode that still meets your outcome. Complexity increases the number of variables you must monitor and the number of places where an edge case can hide.
Environment strategy: separate dev, staging, and production behavior
A reliable configuration approach assumes you will iterate. That means you should avoid using identical settings across every environment without intention. In most teams, the fastest path to stability is to keep development flexible but production constrained and observable.
Use dev to validate assumptions quickly, staging to confirm end-to-end behavior, and production to enforce safety. Even if the feature set is the same, you can differ the thresholds, logging granularity, and protective limits so problems surface early.
When winnoise “” is introduced into an existing workflow, staging becomes your best friend. It lets you confirm that integration points behave correctly (inputs, permissions, dependencies, network constraints, and expected response shapes) before users are impacted.
Logging and diagnostics should be environment-aware
Best practice is not “turn everything on everywhere.” Instead, configure logging levels based on the environment’s purpose. In staging you can be more verbose to accelerate debugging; in production you often want actionable logs without excessive noise.
Look for options related to verbosity, structured logs, correlation identifiers, and error reporting. If the configuration supports it, ensure that failures can be traced end-to-end so you can answer: what happened, where, and why.
Use feature flags for risky configuration changes
If winnoise “” supports enabling or disabling behaviors via configuration switches, treat them like feature flags. That allows you to roll out changes gradually and measure effects before committing to a full rollout.
Feature flags reduce the blast radius of a misconfiguration. Even if a configuration option behaves unexpectedly, you can disable it quickly while preserving overall system availability.
Request and payload handling: avoid hidden bottlenecks
One of the most common reasons configurations fail is that they don’t match real payload characteristics. If your inputs vary in size, structure, or frequency, you must ensure the configuration handles that variance safely.
Review any settings for input validation rules, maximum payload size, schema enforcement, and normalization steps. If validation is too strict, you may reject legitimate inputs. If it is too permissive, you risk downstream errors that are harder to diagnose.
For best results, align your validation rules with what your pipeline truly produces. If your upstream system can guarantee certain shapes, you can keep validation efficient and predictable.
Timeouts, retries, and backoff: configure for stability, not optimism
Timeouts determine how long winnoise “” will wait before concluding that an operation failed. Retries can improve resilience, but they can also amplify load during outages if they are configured too aggressively.
Apply exponential backoff and sensible retry caps when retries are supported. If your configuration allows it, avoid retrying operations that are not idempotent unless your pipeline can guarantee safe replays.
When you tune these options, consider failure patterns: occasional transient network issues may benefit from retries, while persistent downstream misconfigurations may only waste time and worsen the situation.
Performance tuning: measure first, then adjust
Configuration best practices should be evidence-based. That means you should measure baseline performance (latency, throughput, error rates, queue depth, and resource utilization) before changing settings.
Once you establish a baseline, tune the smallest number of parameters needed to address the bottleneck. For example, if latency spikes under load, focus on concurrency-related controls, timeouts, and any buffering behavior.
Be careful with “more is better” settings. Higher concurrency might improve throughput initially, but it can also increase contention, memory usage, and tail latency.
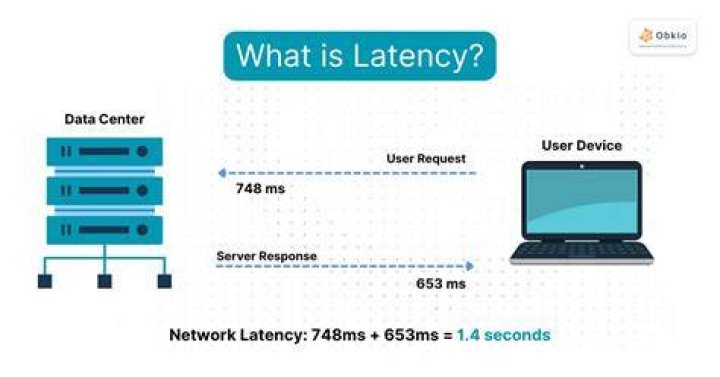
Tail latency matters in real user experiences. If your workload has bursts or variable processing time, test under representative conditions rather than relying only on averages.
Also remember that performance changes often interact with each other. A reduction in retries may lower load during failures, but it can also increase user-visible errors. Tune with the tradeoffs in mind.
Resource limits: align configuration with capacity
If the configuration includes resource limits (such as memory, worker counts, queue sizes, or concurrency ceilings), set them to match your operational capacity. When limits are too low, you will see throttling and queue buildup. When limits are too high, you may cause instability.
Capacity planning doesn’t need to be perfect, but it should be realistic. Start with safe ceilings, then adjust after observing stable operation metrics.
Reliability best practices: reduce error cascades
Reliability is often the most important reason to invest in configuration best practices. Instead of reacting to failures one by one, aim to prevent failures from cascading into bigger incidents.
At the configuration level, that typically means setting guardrails (timeouts, caps, validation rules, fallback behaviors) and ensuring error handling is consistent.
If winnoise “” configuration provides fallback paths, use them thoughtfully. A fallback can improve user experience, but an overly broad fallback can hide systemic problems.
Error handling and consistency checks
Verify that failures return consistent responses. If downstream systems expect a certain error structure, mismatched formats can create additional integration issues.
Also configure reliability around state: if the system uses sessions, context windows, or stored state, make sure your configuration handles state expiration, cleanup policies, and concurrency interactions.
When state is involved, race conditions become configuration risks. Keep state-related options predictable and monitor for anomalies.
Rollout plan: change management for configuration updates
Instead of changing multiple configuration options at once, update one change at a time when possible. This makes it easier to identify the root cause if something behaves differently after a rollout.
Use staged rollout strategies where you can. Start with a small percentage of traffic or a limited set of users, then expand once you confirm that error rates and performance remain stable.
When the rollout finishes, keep monitoring for an additional window. Some issues show up later due to caching patterns, queue behavior, or downstream dependencies.
Security and access controls: configure least privilege
Even when the primary goal is performance or reliability, security configuration choices matter. Ensure that winnoise “” is running with the minimum required permissions to complete its tasks.
Review options related to authentication, authorization, token handling, and secrets management. If the configuration allows specifying allowed sources, validate them to reduce the chance of unintended access paths.
For best practice, separate credentials per environment and rotate secrets on a defined schedule. That prevents a staging credential from accidentally becoming a production risk.
Input trust boundaries
Any system that processes external input should treat it as untrusted by default. Use configuration options that enforce schemas, sanitize or normalize inputs where appropriate, and limit what can be executed or retrieved.
Establish clear boundaries: what winnoise “” is allowed to do based on the request context. When configuration supports context-based rules, use them to constrain behavior.
Maintainability: keep configurations understandable over time
A configuration can work today and become unmanageable tomorrow. That happens when settings are changed repeatedly without clear documentation, naming conventions, or ownership.
Maintain a configuration baseline that includes rationale for key non-default settings. When team members need to modify parameters later, that context prevents accidental regressions.
If your configuration system supports comments or descriptions, use them to explain why an option was chosen. Focus on the “decision,” not the implementation detail.
Document assumptions and invariants
In configuration-heavy systems, assumptions become fragile. For example, you might assume a certain payload format always arrives, or that certain endpoints are stable.
Write down the invariants you rely on. Then when upstream systems change, you have a clear checklist for validating whether winnoise “” still behaves correctly.
Common misconfigurations to watch for
Even with careful setup, a few misconfiguration patterns show up repeatedly across teams. The fastest way to improve reliability is to recognize these patterns early and validate against them during staging.
First, check for mismatched environment settings. A configuration that works in dev might fail in production due to stricter timeouts, different payload sizes, or different access controls.
Second, watch for overly aggressive limits. If you set concurrency too high or timeouts too short, you can produce frequent failures that look like randomness.
Third, verify retries and fallback logic. Retrying the wrong operations can create load spikes, while broad fallbacks can conceal real issues until they grow.
Finally, validate observability. If you can’t correlate errors to specific inputs or workflow steps, troubleshooting becomes slow and uncertain.
Operational best practices after setup
Configuration isn’t a one-time task. After you deploy winnoise “”, you should treat configuration maintenance like an ongoing operational discipline.
Monitor key metrics continuously: error rates, latency distribution (especially p95 or p99), throughput, and any queue/backpressure signals. Then tie alerts to thresholds that reflect user impact rather than internal noise.
When an alert fires, your first job is to confirm whether it’s caused by configuration changes, upstream changes, or external dependency issues. That triage approach prevents unnecessary configuration churn.
Keep an upgrade and rollback path ready
Whenever winnoise “” configuration is updated (or the underlying system changes), ensure you have a rollback plan. That plan should be tested in staging so it’s not theoretical during a real incident.
If configuration changes are versioned, use version comparisons to identify what changed. Rollbacks become much faster when you can quickly map changes to their effects.
Final Thoughts
Getting winnoise “” configured well comes down to deliberate choices: start with the outcomes you want, set safe baseline values, tune with measurement, and manage change carefully across environments. When you treat configuration as a reliability and maintainability tool—not just a setup step—you reduce friction for both users and operators.
If you’re building on a larger rollout, use this supporting guide to complement the pillar resource: use these best practices to make your configuration stable now and easier to evolve later with winnoise.
